Recent & Upcoming Talks

2026

NA

Powering a trial to detect subgroup-by-treatment interactions is, in most realistic scenarios, simply not feasible. At the design stage, investigators presume clinical equipoise, that is they do not expect treatment to harm any group of patients. The overall effect is the weighted average of subgroup-specific effects and the expectation of clinical equipoise sharply constrains how different those effects can be. Under these assumptions, the sample sizes required to detect interactions are dramatically larger than those needed to detect the overall treatment effect. In a trial designed for 80% power on the overall effect, detecting an interaction of comparable magnitude would require at least four times the sample size, and even under ideal conditions, interaction test power hovers around 29%. However, power to detect a subgroup-specific effect is not the same as power to detect an interaction, and these reflect fundamentally different scientific goals. Typically, a patient does not care whether their treatment effect is statistically distinguishable from another subgroup’s, they care whether there is a clinically and statistically meaningful benefit within their own subgroup. Meaningful, valid estimates of subgroup-specific effects are achievable without relying on formal interaction tests, and pre-specifying subgroups and reporting within-subgroup estimates directly is both statistically sound and more aligned with how patients and clinicians actually use trial results.

Symmetric Vaccine Efficacy: Interpretable Estimation and Inference for Vaccine Trials

Traditional measures of vaccine efficacy (VE) are inherently asymmetric, constrained above by 1 but unbounded below. As a result, intervals for VE can extend far below zero, making interpretation challenging and sometimes giving a false impression of evidence that a vaccine is harmful when uncertainty is large. This talk proposes symmetric vaccine efficacy (SVE), a bounded and interpretable alternative to VE that maintains desirable statistical properties while resolving these asymmetries. SVE is defined as a symmetric transformation of observed infection proportions, ensuring estimates remain within (-1, 1) and providing a consistent scale for both beneficial and harmful vaccine effects. We derive a variance and confidence interval for SVE, describe its relationship to traditional VE, and illustrate its application in real trial data. In the example, SVE yields more interpretable uncertainty intervals and clearer graphical summaries compared to standard VE. We then demonstrate open-source tools for computing estimates of SVE and corresponding confidence intervals, available in R through the sve package.

Mind the Gap: Causal Inference is Not Just a Statistics Problem

In this talk we will discuss some of the major challenges in causal inference, and why statistical tools alone cannot uncover the data-generating mechanism when attempting to answer causal questions. We will showcase the Causal Quartet, which consists of four datasets that have the same statistical properties, but different true causal effects due to different ways in which the data was generated. These examples illustrate the limitations of relying solely on statistical tools in data analyses and highlight the crucial role of domain-specific knowledge.

May 12, 2026

12:00 PM – 1:00 PM

Keynote AgStat


By Lucy D'Agostino McGowan in Invited Keynote

slides

Causal Inference in R

This workshop introduces the essential elements of answering causal questions in R. Participants will work through examples of causal inference workflows, learn when standard statistical methods are appropriate and when specialized causal methods are needed, and practice specifying causal questions using Directed Acyclic Graphs (DAGs). The workshop also covers fitting, diagnosing, and applying propensity score models through weighting and matching to estimate causal effects.

Miss(ing) Congeniality: The Cost of Incompatible Imputation Models

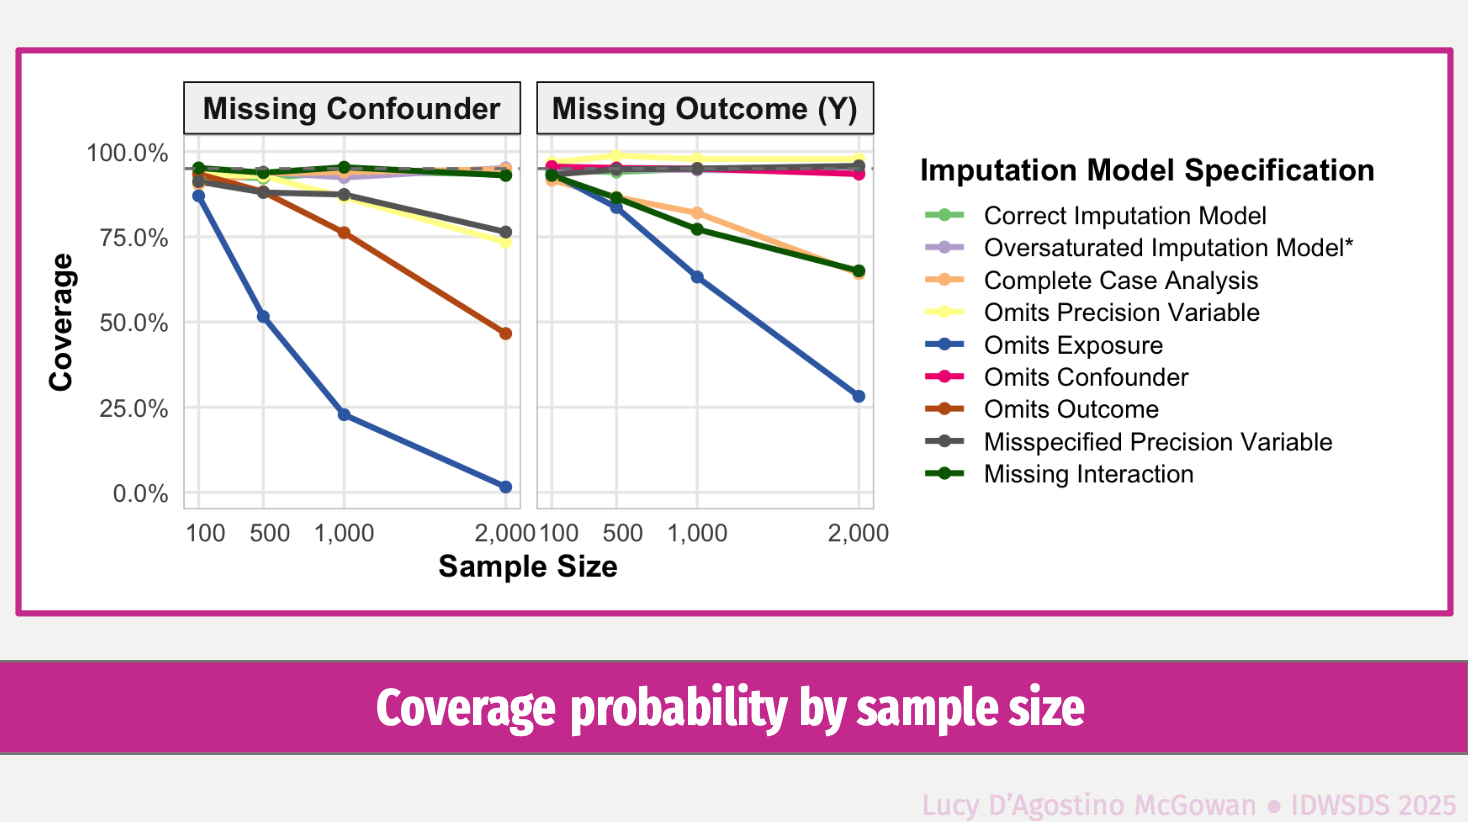
Doubly robust estimators are often viewed as protected against model misspecification, but this protection can fail in the presence of missing data. When multiple imputation is used, lack of congeniality between the imputation and analysis models can induce bias even when both the propensity score and outcome models are correctly specified. Valid inference requires imputation models to include all variables from both the propensity score and outcome models, specified in compatible functional forms. Violations of these conditions can lead to substantial bias in treatment effect estimates. A general framework for combining multiple imputation with doubly robust estimation is presented, the conditions required for congeniality are characterized, and the consequences of misspecification are illustrated. The talk concludes with practical recommendations for specifying imputation models to preserve the validity of doubly robust methods in applied causal analyses.

The Role of Congeniality in Multiple Imputation for Doubly Robust Causal Estimation

This talk provides clear and practical guidance on the specification of imputation models when multiple imputation is used in conjunction with doubly robust estimation methods for causal inference. Through theoretical arguments and targeted simulations, we demonstrate that if a confounder has missing data, the corresponding imputation model must include all variables appearing in either the propensity score model or the outcome model, in addition to both the exposure and the outcome, and that these variables must enter the imputation model in the same functional form as in the final analysis. Violating these conditions can lead to biased treatment effect estimates, even when both components of the doubly robust estimator are correctly specified. We present a mathematical framework for doubly robust estimation combined with multiple imputation, establish the theoretical requirements for proper imputation in this setting, and demonstrate the consequences of misspecification through simulation. Based on these findings, we offer concrete recommendations to ensure valid inference when using multiple imputation with doubly robust methods in applied causal analyses.

April 20, 2026

9:00 AM – 10:00 AM

Distinguished Lecture at Innovations in Design, Analysis, and Dissemination 2026


By Lucy D'Agostino McGowan in Invited Keynote

slides

Causal Inference in R

This workshop provides a structured introduction to causal inference, guiding participants from formulating causal questions to estimating and communicating causal effects using R. Topics include the transition from associational to causal thinking, the role of counterfactuals, and the use of causal diagrams to formalize assumptions. Participants will learn to define causal estimands, implement and diagnose propensity score models, and build outcome models. The workshop also covers methods for continuous exposures, including g-computation, and concludes with approaches to sensitivity analysis. Hands-on exercises in R reinforce each concept, enabling participants to apply modern causal inference techniques in practice.

April 9, 2026

8:30 AM – 5:30 PM

Workshop on Experiments at NEOMA Business School Reims, France 2026


By Lucy D'Agostino McGowan in Invited Workshop

details

2025

The Role of Congeniality in Multiple Imputation for Doubly Robust Causal Estimation

This talk provides clear and practical guidance on the specification of imputation models when multiple imputation is used in conjunction with doubly robust estimation methods for causal inference. Through theoretical arguments and targeted simulations, we show that when a confounder has missing data the corresponding imputation model must include all variables used in either the propensity score model or the outcome model, and that these variables must appear in the same functional form as in the final analysis. Violating these conditions can lead to biased treatment effect estimates, even when both components of the doubly robust estimator are correctly specified. We present a mathematical framework for doubly robust estimation combined with multiple imputation, establish the theoretical requirements for proper imputation in this setting, and demonstrate the consequences of misspecification through simulation. Based on these findings, we offer concrete recommendations to ensure valid inference when using multiple imputation with doubly robust methods in applied causal analyses.

The Art of Data Refinement: Severance Analyses

This talk demonstrates data extraction from multiple sources using the popular television series Severance as an example. For example, we collected and analyzed elevator sounds predict narrative events, voice recordings underwent cepstral analysis to estimate fundamental frequencies and characterize speaker- specific distributions, with k-nearest neighbors used for classification, and text mining was performed on episode scripts to quantify dialogue patterns. These analyses illustrate how statistical methods can be applied to unconventional data sources from entertainment media.

Exploring the Potential of Large Language Models in Generating Saturated DAGs for Causal Inference

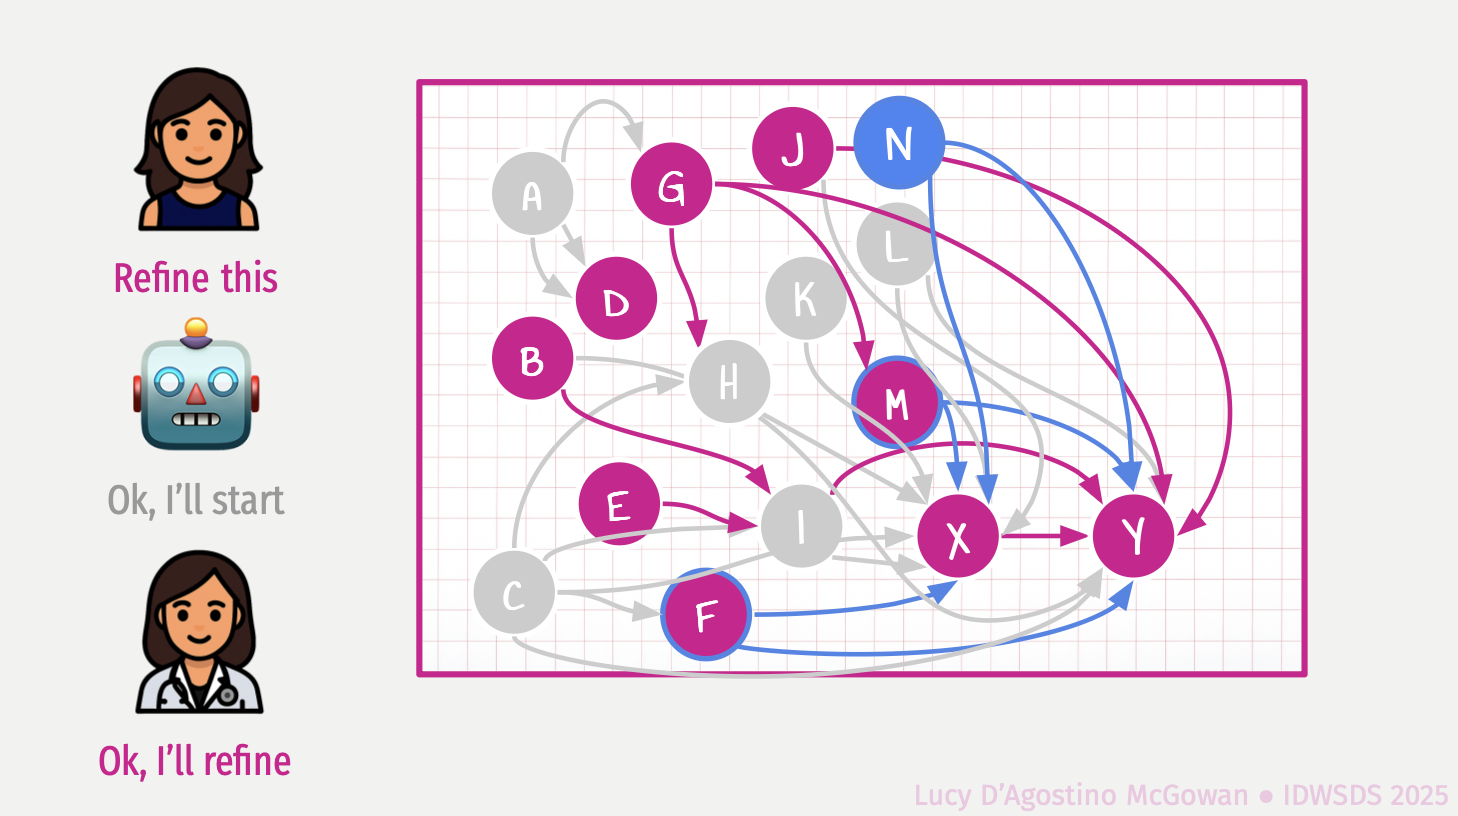
This talk investigates whether large language models (LLMs) could potentially assist in the creation of “saturated DAGs”, graphical representations that exhaustively map all possible causal pathways in a system. We’ll critically examine if and how LLMs might help identify the full space of plausible causal relationships that traditional approaches may overlook. The presentation will assess the strengths and limitations of prompting LLMs to generate comprehensive causal structures, identify backdoor paths, and navigate complex causal systems.